Blog

Deep-dive guides on AI agents, agent orchestration, MCP, and developer tooling.
A row of glowing purple chain links hangs in darkness, with one dark, unlit link at the end, evoking how a single failed run breaks a streak of successes.
Latest · Evals & Benchmarks

pass@k vs pass^k: The Metric That Tells You Whether an Agent Is Reliable

pass@k asks if an agent can solve a task in any of k tries; pass^k asks if it solves it every time. Two agents with the same pass@1 can need opposite fixes, and only pass^k shows which.

November 14, 2026 · 10 min read

Most read this week

  1. AI News & PolicyThe Memory Wall: Why On-Device LLM Inference Is Bottlenecked by Bandwidth, Not Compute
  2. AI News & PolicyDeepSeek, Profiled: How a Quant Hedge Fund's AI Lab Rewrote the Scaling Debate
  3. AI News & PolicyRubin, Ironwood, and the Groq LPU Aren't Competing for the Same Job
  4. AI AgentsHow Background Coding Agents Actually Work: Sandboxes, Diffs, and the PR Review Bottleneck
API Design

Retries Done Right: Exponential Backoff, Jitter and Retry-After

Naive retry loops turn small blips into outages. How exponential backoff, full jitter, Retry-After, idempotency and retry budgets fit together, with worked numbers and a TypeScript helper.

November 13, 2026 · 10 min read
Fintech

Debt Avalanche vs. Snowball: The Real Math, and When the Gap Actually Matters

Avalanche always wins on paper, but by how much depends on your debts. Two worked examples show the snowball costing $154 in one case and $1,789 in another, and why.

November 12, 2026 · 10 min read
Data Formats

UUIDv4 vs UUIDv7 vs ULID: Why Random Primary Keys Hurt Your Index

Random UUIDv4 keys scatter inserts across your B-tree. Here is how UUIDv7 and ULID put a timestamp up front to fix it, with bit layouts, a worked decode and when v4 still wins.

November 11, 2026 · 9 min read
Security

How TOTP Codes Actually Work: The HMAC Math Behind Your Authenticator App

Your phone and a server that never talk after enrollment still agree on the same six-digit code every 30 seconds. Here is the RFC 6238 math that makes it work, with a verifiable example.

October 28, 2026 · 6 min read
LLM Engineering

LiteLLM vs. OpenRouter vs. Portkey: What an LLM Gateway Actually Does Between Your App and the Model

LiteLLM, OpenRouter, and Portkey all promise one API in front of every model provider. Here is how their routing, caching, and failover architectures actually differ once you look past the pitch.

October 27, 2026 · 9 min read
AI Agents

MCP vs. A2A: Why Two "Agent Protocols" Solve Completely Different Problems

MCP and A2A keep getting lumped together as competing agent protocols, but they standardize different layers entirely: one connects an agent to its own tools, the other connects independent agents across a trust boundary. Here's where that line actually falls, and when you need both, one, or neither.

October 26, 2026 · 10 min read
AI News & Policy

DeepSeek, Profiled: How a Quant Hedge Fund's AI Lab Rewrote the Scaling Debate

DeepSeek's R1 release wiped roughly $589 billion off Nvidia's market cap in a single trading day by suggesting frontier-level reasoning didn't require frontier-level spend. Here's what the company actually built, what its cost claims do and don't mean, and why its chip workarounds matter more than its benchmark scores.

October 25, 2026 · 11 min read
AI Agents

How Computer-Use Agents Actually See and Click: Screenshots, Accessibility Trees, and the Grounding Problem

The hard part of a computer-use agent isn't deciding to click "submit"; it's turning that decision into a real coordinate or element reference. Here's how pixel grounding and accessibility-tree grounding actually differ, and where each one breaks.

October 24, 2026 · 7 min read
Applied AI

Where AI Actually Works in Weather Forecasting: AIFS, GenCast, and the Physics Models That Still Won't Retire

ECMWF now runs a machine-learned model operationally next to fifty years of physics code, Google DeepMind's GenCast beats the best physics-based ensemble on 97% of test targets, and NVIDIA has open-sourced its Earth-2 stack. Nobody is using any of it to call a hurricane evacuation.

October 21, 2026 · 7 min read
AI Agents

Durable Execution for AI Agents: How LangGraph, Temporal, Inngest, and DBOS Actually Survive a Crash

AI agent loops run long and cost real money per step, so a naive retry after a crash re-pays for work you already bought. Here is how four durable execution frameworks checkpoint that work, and exactly where each one's recovery model breaks if you trust the default settings.

October 20, 2026 · 12 min read
Applied AI

Where AI Actually Works in Aerospace: Autonomous Rovers, Satellite Vision, and the Flight-Certification Wall

From Mars rovers that pick their own laser targets to satellites that filter their own imagery, aerospace has run AI for a decade in every place a human in the loop is physically impossible, and deliberately kept it out of the cockpit everywhere else.

October 19, 2026 · 8 min read
LLM Engineering

Prompt Versioning and Regression Testing: Why Prompts Need a CI Pipeline Too

A one-line system prompt tweak that 'fixes' one failure case can silently break three others. Here's how teams are starting to treat prompts as versioned, tested artifacts instead of strings in a config file.

October 14, 2026 · 9 min read
AI Agents

Context Engineering: What Changed When Prompt Engineering Outgrew the Prompt

Prompt engineering asked what to say to the model. Context engineering asks what the model actually needs to see, in what order, and what gets thrown away to make room for it: the discipline agents forced into existence.

October 13, 2026 · 7 min read
MCP

MCP Resources: The Primitive Almost No Server Implements

MCP defines three primitives (tools, resources, and prompts), but nearly every server in the wild only implements the first. Here's what resources actually do, why client support lagged, and where skipping them leaves your agent acting on stale context.

October 12, 2026 · 9 min read
Applied AI

Where AI Actually Works in Automotive: Conditional Autonomy, In-Cabin Copilots, and the Humanoid Pilot Problem

From Mercedes' regulator-approved Level 3 Drive Pilot to Tesla's factory-floor humanoid pilots, automotive AI is maturing in wildly uneven bands: production-grade in the paint shop, jurisdiction-limited on the highway, and still experimental in the cabin.

October 11, 2026 · 7 min read
Evals & Benchmarks

METR's Task-Length Benchmark: What "AI Can Now Work for Hours" Actually Means

METR's finding that AI task-completion time horizons double roughly every seven months is the most-cited capability chart in AI. Here's what the 50%-reliability metric behind it actually measures, and what it quietly leaves out.

October 10, 2026 · 7 min read
Applied AI

Where AI Actually Works in Construction: Autonomous Dozers, Progress-Tracking Cameras, and the Liability Wall

From Built Robotics' self-driving excavators on solar farms to Doxel's computer vision catching schedule slip before it's a budget problem, AI is landing in construction in narrow, verifiable ways. The industry's fragmented data and liability exposure keep the broader promise on hold.

October 9, 2026 · 6 min read
LLM Engineering

vLLM, SGLang, or TensorRT-LLM: What Actually Differs When You Self-Host an LLM

vLLM, SGLang, and TensorRT-LLM all promise fast self-hosted inference, but they make different bets on KV cache management, structured output, and hardware lock-in. Here's what actually changes depending on your traffic pattern.

October 8, 2026 · 9 min read
LLM Engineering

Claude Haiku 4.5 vs. GPT-5.4 Mini vs. Gemini 3.8 Flash: The Economics of Cheap Inference

The three labs' cheap-tier models now sit within a quarter-dollar of each other per million input tokens, so the real differences are in release cadence, cache economics, and how much of your "cheap" budget goes to invisible reasoning tokens.

October 5, 2026 · 6 min read
Applied AI

Where AI Actually Works in Travel: Delta's Pricing Fight, Expedia's Romie, and the Hotel Revenue Race

Delta's AI pricing drew a Senate letter, Expedia's Romie can plan a trip but not book one, and hotel revenue management has quietly run on forecasting models for over a decade. Here is what's actually automated in travel versus what's still consumer-facing theater.

October 4, 2026 · 8 min read
MCP

MCP Elicitation: Form Mode, URL Mode, and the Phishing Attack Built Into Its Design

MCP's elicitation feature lets a server pause a tool call to ask the human for more input. The protocol splits it into two modes with very different trust models, one of which exists specifically to stop an account-takeover attack.

October 3, 2026 · 11 min read
LLM Engineering

Fixed-Size, Semantic, or Late Chunking: Where RAG Retrieval Actually Breaks

Most RAG recall failures are decided at the chunking step, long before retrieval or reranking. Here is how fixed-size, semantic, and late chunking actually differ, and when each one silently loses the fact you need.

October 2, 2026 · 9 min read
Applied AI

Where AI Actually Works in Transportation: Robotaxis, Driverless Trucks, and the Traffic Light That Learned to Wait

Waymo's lidar stack, Tesla's vision-only bet, and Zoox's wheel-free pod are chasing the same goal by different routes. Meanwhile, the AI quietly retiming traffic signals and coaching truck drivers is already running at far greater scale.

October 1, 2026 · 7 min read
Applied AI

Where AI Actually Works in Sports: Ball-Tracking Cameras, Injury-Prediction Wearables, and the Line-Calling Controversy

From Hawk-Eye's automated line calls to NFL Next Gen Stats and injury-prediction wearables, AI in sports is mature where there's a verifiable ground truth and shaky everywhere else. That includes the Wimbledon 2025 incident that shows what breaks when it fails.

September 30, 2026 · 8 min read
AI News & Policy

Rubin, Ironwood, and the Groq LPU Aren't Competing for the Same Job

The 2026 AI chip race looks like one contest on a spec sheet, but Nvidia's Rubin, Google's Ironwood, and Groq's LPU are actually built for three different jobs. Comparing their PFLOPS numbers head-to-head misses why each one wins where it does.

September 29, 2026 · 7 min read
API Design

REST vs. RPC-Style API Design: The Tradeoffs Nobody Puts in the Style Guide

Most "REST APIs" in production are actually resource-shaped RPC. Here is what you really give up or gain by choosing REST, JSON-RPC, gRPC, or tRPC for a given piece of your system.

September 28, 2026 · 6 min read
AI News & Policy

Test-Time Compute Scaling: Why Letting a Model "Think Longer" Sometimes Beats Making It Bigger

A 2024 DeepMind study found that spending more compute at inference time, not training time, can let a small model match one many times its size on math problems. Here's the mechanism, and why it only works in a narrow band of difficulty.

September 27, 2026 · 8 min read
AI News & Policy

Colorado, California, Texas: Mapping the 2026 US State AI Law Patchwork

Texas bans specific AI uses, California regulates frontier model developers, and Colorado rewrote its flagship AI law under litigation pressure. Here's what each actually requires, and why Trump's preemption executive order hasn't changed any of it yet.

September 26, 2026 · 9 min read
Applied AI

Where AI Actually Works in Telecom: Self-Organizing Networks, Robocall Detection, and the RAN Latency Problem

From antennas that retune themselves in milliseconds to the scam-call filter that silently screens your phone, telecom runs some of the largest and least forgiving ML deployments in production. Almost none of it looks like a chatbot.

September 25, 2026 · 8 min read
AI News & Policy

Perplexity's Browser Bet: Why It Doubled Down on Comet the Same Summer OpenAI Killed Atlas

When OpenAI shut down its ChatGPT Atlas browser in August 2026, Perplexity was raising money at a $30B+ valuation to build Comet into the opposite bet: that the AI browser, not the chat window, is where the agent economy actually lives.

September 24, 2026 · 9 min read
Fintech

Compound vs. Simple Interest: Why the Same Rate Can Mean Different Money

Two loans with the identical 6% rate can differ by thousands of dollars in total interest. The gap comes entirely from how (and how often) that interest compounds, worked through with real numbers.

September 23, 2026 · 5 min read
API Design

Designing Sane Pagination: Why Offset Breaks Under Writes and Keyset Fixes It

LIMIT/OFFSET pagination silently duplicates and skips rows the moment writes happen concurrently, and gets slower the deeper a client pages. Here is why, and how keyset (cursor) pagination avoids both problems.

September 20, 2026 · 6 min read
Applied AI

Where AI Actually Works in Gaming: Voice Moderation, NPC Dialogue, and the Procedural Generation Reality Check

Call of Duty already runs AI on live voice chat to catch harassment in real time, and Microsoft trained a world model on years of Xbox gameplay. But the 'AI will write your NPCs and build your levels' pitch is running years ahead of what's actually shipping.

September 19, 2026 · 8 min read
AI Agents

How Background Coding Agents Actually Work: Sandboxes, Diffs, and the PR Review Bottleneck
Codex, Copilot's cloud agent, Cursor's cloud agents, Jules, Devin, and cloud Claude Code sessions all follow the same five-stage pipeline. The differences that matter are in sandbox scope, repo access, and where the real trust boundary sits.
September 18, 2026 · 11 min read
Applied AI

Where AI Actually Works in Marketing: Programmatic Bidding, Generative Creative, and the Attribution Crisis

From Performance Max's black-box bidding to Coca-Cola's uncanny AI holiday ad, marketing bet on AI years before it had reliable measurement to prove any of it works. Here's where it actually delivers, and where attribution is still the unsolved problem.
September 17, 2026 · 8 min read
Applied AI

Where AI Actually Works in Government: Citizen Chatbots, Fraud Detection, and the Due-Process Problem

Government AI splits into two very different tracks: citizen-facing chatbots that have to be boring and accurate, and back-office risk-scoring systems that have already produced real due-process failures. Here's how each actually works today.
September 16, 2026 · 6 min read
Applied AI

Where AI Actually Works in Real Estate: The Zestimate Reckoning, AI Leasing Agents, and the New Disclosure Laws

Zillow lost over $500 million learning that a pricing model is not a trading strategy. Five years later, AI has quietly taken over apartment leasing and lease abstraction, while a new wave of state laws forces agents to label every AI-touched photo.
September 15, 2026 · 8 min read
AI Agents

Langfuse vs. Braintrust vs. Arize Phoenix: Picking an LLM Observability Stack in 2026

Three tools dominate LLM/agent observability right now, each built around a different bet: open self-hosting, eval-driven CI/CD, or OpenTelemetry portability. Here is what the pricing table does not tell you.
September 14, 2026 · 6 min read
Applied AI

Where AI Actually Works in Energy: Forecasting, Digital Twins, and the Datacenter That Learned to Negotiate With the Grid

AI is already reshaping the power sector, but the clearest wins are boring forecasting and maintenance systems, not the AI-controls-the-grid story. The newest twist is AI datacenters themselves being turned into flexible grid assets.
September 13, 2026 · 9 min read
Security

How AI Coding Agents Actually Sandbox Code Execution: gVisor, Firecracker, and What Docker Alone Doesn't Stop

Coding agents now run arbitrary, LLM-generated code by default (npm install, test suites, shell one-liners), which turns "sandbox untrusted code" from an occasional need into a load-bearing part of the architecture. Here's what actually stands between an agent's code and your host kernel.

September 12, 2026 · 9 min read
MCP

MCP Sampling: How a Server Asks the Client's Model to Think for It

Sampling is the MCP primitive that inverts the relationship, letting a server without its own model borrow the client's LLM through a two-gate approval flow. Here is how it works, and why the 2026-07-28 spec revision deprecated it.
September 11, 2026 · 9 min read
Applied AI

Where AI Actually Works in Journalism: Automated Earnings Reports, the Traffic Collapse, and the Fake-Byline Scandals

From Bloomberg's decade-old earnings-report bot to Sports Illustrated's fabricated AI bylines, AI in newsrooms splits cleanly into what works and what blew up. Meanwhile, AI answer engines are quietly absorbing the referral traffic that used to fund it all.

September 10, 2026 · 7 min read
AI Agents

LangGraph, CrewAI, OpenAI Agents SDK, Claude Agent SDK: Four Different Bets on How Agents Should Talk to Each Other

Four multi-agent frameworks, four incompatible answers to the same question: when one agent hands work to another, what happens to the context? The choice determines what breaks in production.
September 9, 2026 · 8 min read
Applied AI

Where AI Actually Works in Logistics: Route Optimization, Driverless Freight, and the Data-Quality Wall

Driverless trucks are now billing customers on real Texas highways, not just demoing for reporters. Here's what's actually shipped in logistics AI versus what's still a slide deck.
September 8, 2026 · 8 min read
API Design

OpenAPI Spec-Driven Development: The Contract That Keeps Your API and Docs From Diverging

Code-first and spec-first OpenAPI workflows fail in different ways, and neither prevents contract drift unless linting and contract tests are actually wired into CI.

September 7, 2026 · 6 min read
Applied AI

Where AI Actually Works in Agriculture: Precision Spraying, Autonomous Tractors, and the Connectivity Problem

From John Deere's weed-targeting cameras to Merck's livestock wearables, the AI actually deployed on farms today is narrow and sensor-heavy. It keeps running into the same wall: rural connectivity, capital cost, and fields that don't hold still for a model.

September 6, 2026 · 7 min read
Data Formats

UTF-8 vs. UTF-16: Why UTF-8 Won and What Surrogate Pairs Actually Are

Why does "😀".length return 2 in JavaScript but 1 in Python? The answer is a 1990s encoding decision that still causes truncation bugs, MySQL charset gotchas, and broken emoji today.

September 5, 2026 · 7 min read
AI Agents

Letta, Mem0, and LangGraph Stores: Three Different Answers to Where Agent Memory Lives

Letta, Mem0, and LangGraph checkpointers all get called "agent memory," but they put the decision to remember or forget in three different places: an agent runtime, an external service, or your own application code.
September 4, 2026 · 8 min read
Applied AI

Where AI Actually Works in Hiring: Resume Screening, Interview Scoring, and the Bias Audit Laws Catching Up to It

From Workday's algorithmic screening lawsuit to NYC's mandatory bias audits, AI hiring tools are now mature enough to be regulated, and the regulations are starting to bite.
August 26, 2026 · 8 min read
Evals & Benchmarks

LLM-as-Judge Evaluations Have Five Known Biases: Here's How to Design Around Them

Position bias, verbosity bias, and self-preference bias can silently distort agent eval scores. Here is how to design a judge pipeline that resists them, plus why trajectory evaluation catches what outcome scoring misses.
August 25, 2026 · 10 min read
LLM Engineering

How Constrained Decoding Actually Forces an LLM to Emit Valid JSON

Structured outputs and strict tool use aren't prompting tricks. They mask invalid tokens at the decoding layer so malformed JSON becomes mechanically impossible, not just less likely.

August 24, 2026 · 10 min read
Applied AI

Where AI Actually Works in Retail: Cashierless Checkout's Walkback, Demand Forecasting, and the Personalization Ceiling

Amazon quietly pulled Just Walk Out from most of its Fresh stores in 2024, which makes a good starting point for separating retail AI that actually works from the version in the marketing copy.
August 23, 2026 · 7 min read
Applied AI

Where AI Actually Works in Insurance: Claims Photos, Underwriting Models, and the NAIC Compliance Gap

AI in insurance is furthest along in the parts of the workflow farthest from a payout decision, like damage photos and fraud flags. It stalls hard exactly where a model output decides who gets paid or covered.
August 21, 2026 · 9 min read
Applied AI

Where AI Actually Works in Cybersecurity: SOC Copilots, Anomaly Detection, and the Autonomous Response Gap

AI has clearly won in security alert triage and code scanning, is mature but unglamorous in behavioral anomaly detection, and is still narrowly scoped in autonomous incident response. Here is why the adoption curve breaks exactly where human sign-off stops.

August 20, 2026 · 7 min read
AI Agents

Most Tool-Calling Failures Are Schema Failures, Not Model Failures

When an LLM agent calls the wrong tool or sends malformed arguments, the postmortem usually blames the model. The actual defect is almost always in the JSON Schema the tool was registered with.

August 19, 2026 · 9 min read
Data Formats

YAML's Whitespace Footguns: Why the Norway Problem and Tab Indentation Keep Breaking Configs

YAML's indentation-as-syntax and implicit type inference make it readable to write and dangerous to get subtly wrong. Here's why 'NO' becomes false, why tabs are banned, and why 1.10 silently becomes 1.1.
August 19, 2026 · 7 min read
AI News & Policy

Nvidia's $20 Billion Groq Deal: How a 'Reverse Acquihire' Buys Chip Talent Without Triggering Antitrust Review

Nvidia paid roughly $20 billion for a non-exclusive license to Groq's inference chip technology and hired its two top executives, while Groq itself stays a nominally independent company. Here's what was licensed, why the structure matters more than the price tag, and what it signals about how dominant tech companies now avoid merger review.

August 12, 2026 · 7 min read
API Design

Webhook Signature Verification: How Stripe, GitHub, and Svix Actually Stop Forged Events

A webhook endpoint is just a public URL that runs code when it receives a POST, so anyone who finds it can send you fake events unless you verify the signature correctly, including the two checks most implementations skip.
August 11, 2026 · 6 min read
Data Formats

JSON Schema in Practice: What allOf, oneOf, and additionalProperties Actually Do

JSON Schema looks like static typing for JSON, but its composition keywords follow evaluation rules that trip up most people writing their first real-world schema. Here's the mental model that actually holds up.
August 10, 2026 · 6 min read
AI News & Policy

AI Copyright Litigation, Mapped: Where Fair Use Actually Stands After the Anthropic Settlement

A field guide to the AI training-data lawsuits that have actually produced rulings (Thomson Reuters v. Ross, Bartz v. Anthropic, Kadrey v. Meta, Getty v. Stability) and what they do and don't establish for anyone building on top of a foundation model.
August 9, 2026 · 8 min read
AI Agents

Tracing an Agent Loop: What OpenTelemetry's GenAI Conventions Actually Standardize

Agent traces have a runtime-decided shape, token-based cost, and cross-process tool hops that conventional APM was never built for. Here is what OpenTelemetry's gen_ai.* conventions actually pin down, and where tracing an agent loop still breaks in production.

August 8, 2026 · 10 min read
Fintech

ROI vs. IRR vs. Payback Period: Why the "Best" Investment Depends on Which One You Ask

Three investments, three different "winners" depending on which metric you compute. Here is the arithmetic behind ROI, IRR, and payback period, and exactly when each one lies to you.
August 7, 2026 · 6 min read
Fintech

The IBAN Checksum Explained: How Mod-97 Catches a Mistyped Bank Account Before It Costs You

IBANs aren't just a longer account number: two check digits form a mod-97 checksum that catches typos and transposed digits before a wire transfer goes to the wrong bank. Here's the actual arithmetic, worked through on a real-looking IBAN.

August 6, 2026 · 6 min read
MCP

MCP Authorization: How OAuth 2.1 Actually Secures a Remote MCP Server

MCP started as a trusted local subprocess with no auth story at all. Its authorization spec bolts on OAuth 2.1, PKCE, and resource indicators; here is what each piece actually prevents, including the token-passthrough bug that keeps showing up in early implementations.

August 5, 2026 · 9 min read
Security

JWK Rotation in Production: What Actually Breaks When You Rotate a Signing Key

Rotating a JWT signing key is a distributed cache-invalidation problem wearing a cryptography costume. Here is the four-stage timeline, the kid collision that breaks it silently, and why your overlap window is set by your slowest verifier cache, not your token TTL.

August 4, 2026 · 8 min read
Evals & Benchmarks

What SWE-bench Actually Measures vs. What the Leaderboard Tells You

SWE-bench is the most credible agentic coding benchmark available, but its leaderboard number answers a narrower question than most headlines imply. Here is exactly what it does and does not test.
August 3, 2026 · 9 min read
Applied AI

Where AI Actually Works in Scientific Research: Protein Design, Materials Discovery, and the GNoME Lesson

AlphaFold's Nobel Prize and GNoME's 2.2 million materials both got real headlines, but the honest story is about candidate generation, not discovery, and the gap between those two claims is where the hype lives.
August 2, 2026 · 7 min read
LLM Engineering

Claude Sonnet 5 vs. GPT-5.6 vs. Gemini 3.1 Pro: What the Pricing Table Doesn't Tell You

A side-by-side look at pricing, context windows, and tiering across the three frontier model families as of August 2026, and why the spec sheet undersells how differently they actually behave in agent loops.
August 1, 2026 · 7 min read
Fintech

Margin vs. Markup: The Pricing Mistake That Quietly Eats Small-Business Profit

A 25% markup and a 25% margin are not the same number, and mixing them up systematically underprices every product you sell. Here's the actual math, a worked example, and why the confusion never seems to die.
July 31, 2026 · 5 min read
Security

Why Your Email Regex Is a Denial-of-Service Waiting to Happen

Catastrophic backtracking turned a routine validation regex into Cloudflare's 2019 global outage. Here is the exact pattern shape that causes it, why email regexes are especially prone to it, and which engines make the bug impossible.
July 30, 2026 · 6 min read
Applied AI

Where AI Actually Works in Media Production: Dubbing, Pre-Viz, and the De-Aging Ceiling

Generative AI has already reshaped dubbing, pre-visualization, and de-aging in film and video production, but full synthetic performers and one-click final-pixel VFX are still blocked by consistency, rights, and labor agreements, not just model quality.

July 29, 2026 · 7 min read
Applied AI

Where AI Actually Works in Customer Support: Deflection, Copilots, and the Outcome-Pricing Bet

Klarna's AI assistant did the work of 700 agents, then the company started rehiring humans. The real story is that support AI succeeds in narrow, policy-bounded tiers and breaks hard the moment it touches judgment calls and liability.

July 28, 2026 · 6 min read
AI News & Policy

Mistral AI, Profiled: The Product Isn't the Model, It's the Deployment Terms

ASML led a ~€1.7B round in Mistral AI in 2025: an industrial policy trade dressed as a venture round. A grounded look at what the Paris lab actually ships, why sparse MoE was the right asymmetric bet, and where the open-weight-plus-sovereignty strategy is fragile.
July 27, 2026 · 7 min read
AI News & Policy

Your Model's Reasoning Trace Is Not a Log: What Chain-of-Thought Faithfulness Research Actually Shows

Reasoning models write confident step-by-step explanations that often omit the thing that actually changed their answer. Here's the experimental evidence, the mechanism behind it, and which of your uses of chain-of-thought survive it.
July 26, 2026 · 7 min read
Applied AI

Where AI Actually Works in Manufacturing: Warehouse Robots, Defect Vision, and the Humanoid Reliability Math

Factories have been automated since the 1970s, so AI is landing only where classical automation always broke: unfixtured parts, unseen defects, and machines with no failure history. A grounded look at what is in production versus what is still a single-task pilot.

July 25, 2026 · 9 min read
Security

JWT vs Session Cookies: The Trade Isn't Statelessness, It's Revocation

"JWTs are stateless, so they scale better" is the sentence that leads teams straight into the logout-doesn't-work bug. Here's the real trade-off, the revocation problem it creates, and when each auth model is actually the right call.
July 22, 2026 · 6 min read
Data Formats

Base64 vs Base32 vs Base58: Why Bitcoin Doesn't Use the Encoding Your API Does

Base64, Base32, and Base58 all turn bytes into printable text, but they solve different problems. Two chop the bitstream; one converts the whole thing as a big number, and that single distinction decides which belongs in front of a human.
July 21, 2026 · 7 min read
Applied AI

Where AI Actually Works in Education: Tutoring, Grading, and the Detection Problem That Won't Die

AI tutoring, autograding, and language apps are shipping to millions of students, while AI-cheating detectors keep getting disabled. A grounded look at what works, what doesn't, and the boundary that explains both.
July 20, 2026 · 8 min read
Fintech

How Amortization Actually Works: Why Two Loans at the Same Rate Cost Different Amounts

Two borrowers with identical 6% mortgages can pay $156k or $348k in interest. The rate isn't the culprit; the term and the amortization schedule are, and here's the math with real numbers.
July 19, 2026 · 5 min read
AI News & Policy

The Memory Wall: Why On-Device LLM Inference Is Bottlenecked by Bandwidth, Not Compute

Your phone's NPU isn't the reason local LLMs feel slow; the memory bus is. Here's why token generation is bandwidth-bound, and why quantization, KV-cache tricks, and unified memory are all attacks on the same wall.
July 18, 2026 · 9 min read
API Design

Idempotency Keys: Why 'Just Retry the Request' Breaks in Production

A dropped connection makes a client retry a POST that already succeeded, and without an idempotency key that retry becomes a duplicate charge, not a safety net. Here's how the pattern actually works and where naive implementations fail.
July 15, 2026 · 6 min read
Applied AI

Where AI Actually Works in Legal: Contract Review, E-Discovery, and the Hallucination Problem Courts Keep Catching

From the Mata v. Avianca fake-citation scandal to court-validated e-discovery, legal AI has converged on one design rule: never trust an unsourced answer. Here is where that constraint has produced real deployments, and where it hasn't.

July 14, 2026 · 6 min read
Data Formats

NDJSON vs JSON Arrays for Streaming: Why the Trailing Bracket Is the Problem

A JSON array requires seeing the closing bracket before any of it is valid, which is exactly what breaks when you stream millions of records. Newline-delimited JSON fixes that by making every line a complete, independent document.
July 13, 2026 · 6 min read
Applied AI

Where AI Actually Works in Healthcare: Scribes, Imaging Triage, and Drug Discovery

From ambient documentation that saves physicians hours a day to an FDA-authorized system that diagnoses diabetic retinopathy with no doctor in the loop, AI has real footholds in healthcare. The Epic sepsis model shows exactly where those footholds end.

July 12, 2026 · 7 min read
AI Agents

How AI Coding Assistants Actually Work: Context, Diffs, and Permission Boundaries

AI coding assistants aren't one architecture. They're three separable design decisions (how context gets assembled, how edits get applied, how execution gets contained) that every tool from Claude Code to Cursor answers differently.
July 11, 2026 · 8 min read
Security

bcrypt vs scrypt vs Argon2: How Password Hashing Actually Differs

MD5 and SHA-256 are fast, and fast is exactly the wrong property for password storage. Here is how bcrypt, scrypt, and Argon2 slow attackers down differently, and how to actually pick between them.

July 10, 2026 · 8 min read
Applied AI

Where AI Actually Works in Finance: Fraud Scoring, Underwriting, and the Klarna Walkback

Fraud detection, credit underwriting, and algorithmic trading all use "AI" today, but the maturity, autonomy, and regulatory scrutiny at each stop are wildly different. The most-hyped win, Klarna's chatbot, had to be walked back.

July 9, 2026 · 8 min read
Fintech

The Luhn Algorithm Explained: How Credit Card Numbers Catch Their Own Typos

The Luhn checksum baked into every credit card number catches keystroke errors, not fraud. Here is the math behind it, why card network prefixes matter, and where naive validators break.

July 8, 2026 · 6 min read
LLM Engineering

Prompt Engineering for Agents Is a Different Discipline Than Prompt Engineering for Chat

In agent systems, instructions live across four surfaces (system prompt, tool schemas, tool results, and few-shot text), not one. Most prompt debugging still only looks at the first.
July 7, 2026 · 7 min read
AI Agents

Context Compaction: How Long-Running Agents Avoid Drowning in Their Own History

Long-running agents rarely fail because they run out of context window; they fail because nobody designed what happens to attention quality once the transcript outgrows what the model can usefully weigh. Here is how tiered compaction, tool-output pruning, and sub-agent isolation actually work.

July 6, 2026 · 7 min read
LLM Engineering

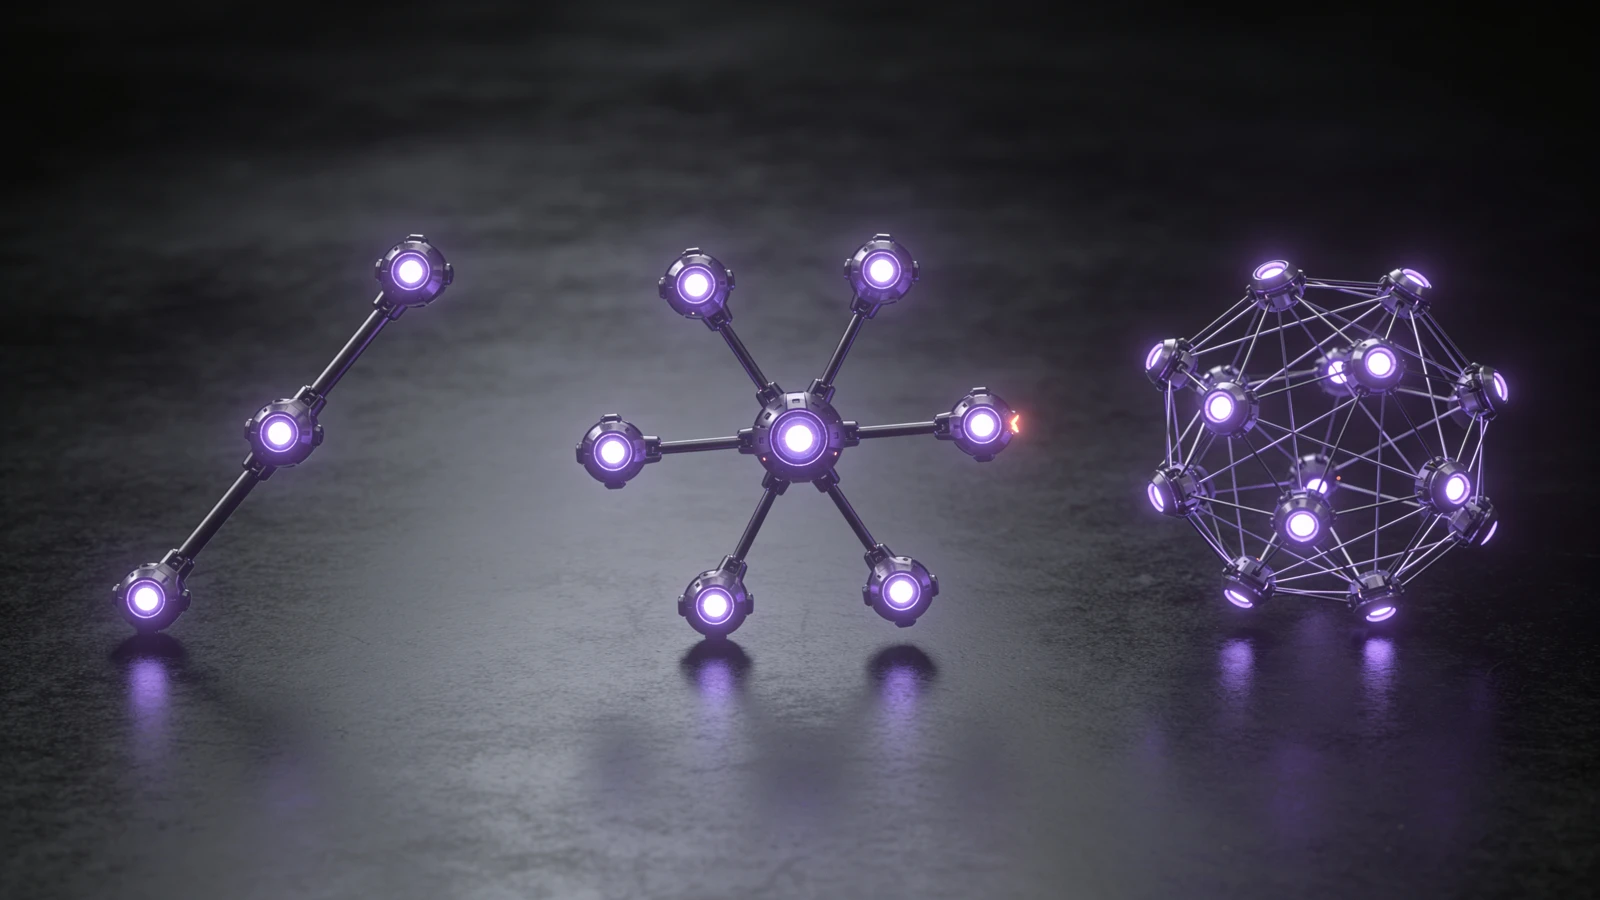
Naive RAG, Agentic RAG, and GraphRAG: What Actually Changes Architecturally

RAG is not one architecture; it is three structurally different systems with different costs and failure modes. Here is what actually changes between naive, agentic, and graph-based retrieval, and how to pick without over-building.
July 5, 2026 · 7 min read
AI Agents

Pipeline, Supervisor, or Mesh: Where Each Multi-Agent Orchestration Pattern Actually Breaks

The three dominant multi-agent orchestration topologies each fail in a different, predictable way once you move past the demo. Here is how to pick one based on where your task actually breaks, not which pattern sounds more sophisticated.

July 4, 2026 · 8 min read
AI News & Policy

The EU AI Act's High-Risk Rules Moved to December 2027: What Actually Changes for Builders

The EU AI Act high-risk obligations were due on August 2, 2026, until the AI Omnibus moved Annex III to December 2, 2027. Here is what is required, of whom, and how it compares with the US, UK, and China.
July 3, 2026 · 8 min read
LLM Engineering

KV Cache Reuse and the Hidden Latency Budget of Agent Loops

Agent latency is usually a prompt-construction problem in disguise: prefix caching, continuous batching, and tool-call structure determine how much of your context gets reprocessed on every turn.

July 2, 2026 · 8 min read
Security

The Trust Boundary Problem: Why Tool-Calling Agents Need to Treat Tool Output as Untrusted Input

Most agent security advice targets prompt injection at the wrong layer. The real fix is architectural: separate untrusted tool output from privileged context, scope tool capabilities narrowly, and gate side-effecting actions behind confirmation.

July 2, 2026 · 8 min read
Evals & Benchmarks

Why Your Agent Benchmark Score Doesn't Predict Production Reliability

Benchmark leaderboards measure task completion under lab conditions, not the compounding step failures that sink agents in production. Here is the math, and a blueprint for an eval harness that actually predicts reliability.
July 1, 2026 · 7 min read
AI Agents

Agent Memory Isn't RAG: Why Vector Retrieval Falls Apart for Stateful Agents

Vector similarity search answers what text is topically related, but long-running agents need to know what is true right now. Conflating the two is why agents keep resurrecting overturned decisions.
June 30, 2026 · 7 min read
MCP

What Actually Happens Inside an MCP Tool Call

A wire-level look at the Model Context Protocol: capability negotiation, tool discovery, transport tradeoffs, and the context-budget mistakes that quietly degrade agent reliability.

June 29, 2026 · 8 min read

New posts by email

One email when a new post goes up. No other mail; unsubscribe in one click.

We store your email only to send new posts. See the privacy policy.